Affiliate disclosure: some links in this article are partner links. If you start a paid plan through them, imisofts may earn a commission at no extra cost to you. We only recommend tools we actually use to run client campaigns.
Short answer. Perplexity ended support for Sonar Chat Completions on 27 September 2026, and its pricing page no longer lists a Sonar rate. Synchronous and streaming Sonar calls still work while Perplexity reformulates them as Agent API requests, model by model; asynchronous Sonar calls are no longer supported. On the Agent API you pay each model's per-token rate plus tool fees: $2.50 per 1,000 web search calls, or $1.00 with Fast Search, and $0.50 per 1,000 page-fetch calls. The standalone Search API costs $5 per 1,000 requests, or $1 with Fast Search, with no token charges. Perplexity's own benchmark tables put its cheapest preset, fast, at $0.0014 to $0.0018 per request, against $0.0059 to $0.0070 for Sonar. We earn a commission if you buy Apify or Bright Data through our links; Perplexity pays us nothing.
Every price and limit below was read on 19 October 2026 on Perplexity's, Apify's and Bright Data's own pages; the totals are our arithmetic. We did not run billed tests on any of the three or test answer quality.
Key numbers
| Item | Number |
|---|---|
| Sonar Chat Completions support ended (sync and streaming calls being reformulated as Agent API requests, model by model; async no longer supported) | 27 September 2026 |
| Agent API web_search, per 1,000 invocations (plus model tokens; fetch_url $0.50 per 1,000) | $2.50, or $1.00 with Fast Search |
| Search API, per 1,000 successful requests (up to five queries per request; no token charges) | $5, or $1 with Fast Search |
| GPT-6 Luna tokens on the fast preset, per million (up to 272K input; priority tier, twice the listed $0.10 and $0.50) | $0.20 in, $1.00 out |
| Old Sonar rate card, request fee per 1,000 (by search context size, plus $1 per million tokens in and out) | $5, $8 or $12 |
| Old Sonar Pro rate card, per million tokens (plus $6 to $14 per 1,000 requests) | $3 in, $15 out |
| Fast preset cost per request, Perplexity benchmarks (undated; Sonar: $0.0059 to $0.0070; Bright Data SERP results alone, pay as you go: $0.0015) | $0.0014 to $0.0018 |
| high preset vs Sonar Deep Research, per request (BrowseComp; DeepSearchQA: 22% and 21% of the cost) | $0.136 vs $0.611; $0.121 vs $0.5656 |
| xhigh preset vs Sonar Deep Research, BrowseComp (28% more, scoring 85.33% vs 29.10%; 61% less on DeepSearchQA) | $0.78 vs $0.611 per request |
| Agent API rate limit, Tier 0 to Tier 5 (Tier 1 from $50 of credits; Tiers 4 and 5 both 33) | 1 to 33 requests per second |
| Bright Data SERP API, pay as you go (5,000 free credits a month, shared; Scale $499 for 380,000) | $1.50 per 1,000 requests |
| Apify RAG Web Browser, per 1,000 default queries (at most; Business ($999 a month) to Free, through Standby; up to three pages each) | $6.02 to $10.32 |
Prices and limits read on 19 October 2026 from Perplexity's pricing, Agent API, presets, benchmark, changelog and rate-limit docs, its help center and API terms, Bright Data's SERP API page and free-tier docs, and Apify's RAG Web Browser pages; totals are our arithmetic. Apify and Bright Data pay us a commission; Perplexity does not.
What happened to Sonar
Perplexity's migration guide says Sonar Chat Completions support ended on 27 September 2026. Synchronous and streaming requests keep working and are being reformulated as Agent API requests, rolling out gradually by model. Asynchronous Sonar requests are no longer supported and need to move to the Agent API's background mode. The changelog tagged the migration as a deprecation in July 2026.
Sonar the model has not disappeared: perplexity/sonar is listed inside the Agent API at $0.25 per million input tokens and $2.50 per million output tokens, with web search billed separately. What has ended is support for Sonar Chat Completions, and its rate card is off the pricing page. Perplexity suggests these presets as starting points:
| Sonar model | Suggested preset | What the preset runs today |
|---|---|---|
| Sonar | fast | GPT-6 Luna, 1 step, priority tier, Fast Search, 10 results |
| Sonar Pro | fast | Same as above |
| Sonar Reasoning Pro | low | GPT-6 Luna, up to 5 steps, Fast Search plus page fetch |
| Sonar Deep Research | high | GPT-6 Sol, up to 15 steps, Fast Search plus page fetch |
Above high sits xhigh, which runs Claude Opus 5.5 for up to 100 steps with standard web search, finance search and a code sandbox.
Two migration details change the bill. Sonar's search_context_size setting has no named equivalent; the Agent API's web search tool takes token budgets instead, and you are charged for the exact number of search context tokens consumed, not the budget you set. And presets are dynamic: Perplexity updates a preset's configuration, which can include its model, as evals show improvements, aiming to stay in the same cost band, unless you copy the preset's current values into a frozen configuration.
Perplexity API prices on 19 October 2026
The pricing page now covers the Search, Agent, Orchestrator, Embeddings and Decisions APIs. From the pricing and Agent API models pages, the lines most relevant to Sonar users:
| Item | Listed price | Billing unit |
|---|---|---|
| GPT-6 Luna (fast, low and medium presets) | $0.10 in, $0.50 out | Per million tokens, up to 272K input |
| GPT-6 Sol (high preset) | $2 in, $10 out | Per million tokens, up to 272K input |
| Claude Opus 5.5 (xhigh preset) | $4 in, $20 out | Per million tokens |
| perplexity/sonar | $0.25 in, $2.50 out | Per million tokens |
| web_search | $2.50, or $1.00 with Fast Search | Per 1,000 invocations |
| fetch_url | $0.50 | Per 1,000 invocations |
| people_search, finance_search | $5 | Per 1,000 invocations |
| sandbox | $0.03 | Per session, a 20-minute billing window |
| Search API | $5, or $1 with Fast Search | Per 1,000 successful requests |
Priority processing bills twice the listed token price and flex half, on models that support those tiers; GPT-6 Luna and GPT-6 Sol do, Claude Opus 5.5 lists neither. The fast preset runs on priority, so its GPT-6 Luna tokens bill at $0.20 and $1.00 per million.
The Search API bills each successful request, and one request can carry up to five queries for the price of one. It does not bill invalid, rate-limited or upstream-failed requests, but it does bill a successful response that returns no results. It returns 10 ranked results by default, up to 20.
The old Sonar rate card, and what we could not confirm
The pricing page no longer shows Sonar, but a copy of its rate card remains in the data behind the pricing calculator on Perplexity's Agent API Models page:
| Sonar model | Tokens in / out, per million | Request fee per 1,000 (low / medium / high context) |
|---|---|---|
| Sonar | $1 / $1 | $5 / $8 / $12 |
| Sonar Pro | $3 / $15 | $6 / $10 / $14 |
| Sonar Reasoning Pro | $2 / $8 | $6 / $10 / $14 |
| Sonar Deep Research | $2 / $8 | None; $2 per million citation tokens, $3 per million reasoning tokens, $5 per 1,000 searches |
Sonar's per-request fee was tiered by search context size. We could not confirm whether reformulated Sonar calls now bill on this card or at Agent API rates, or whether Sonar also billed search content as tokens; the Agent API does.
Google's AI Overview for "perplexity api pricing" (US English) told us on 19 October that standard Sonar models carry no per-request search fees and that search and citations are included in the per-token price. Its token rates match the card above, but that card carries request fees of $5 to $14 per 1,000, and the Agent API bills every web search as its own line.
What a request costs on Perplexity's benchmarks, by preset
Perplexity's benchmark page prices each Sonar model and preset per request on its own workloads, with no date, model or preset versions given:
| Configuration | BrowseComp score, cost per request | DeepSearchQA score, cost per request |
|---|---|---|
| Sonar | 7.00%, $0.0070 | 27.26%, $0.0059 |
| Sonar Pro | 7.33%, $0.0156 | 30.11%, $0.0209 |
| Sonar Reasoning Pro | 16.33%, $0.0163 | 38.41%, $0.0260 |
| Sonar Deep Research | 29.10%, $0.611 | 48.94%, $0.5656 |
| fast preset | 26.67%, $0.0014 | 53.30%, $0.0018 |
| low preset | 48.67%, $0.0060 | 64.90%, $0.0120 |
| medium preset | 71.67%, $0.0160 | 85.90%, $0.0310 |
| high preset | 78.00%, $0.136 | 89.60%, $0.121 |
| xhigh preset | 85.33%, $0.78 | 93.00%, $0.218 |
On Perplexity's own workloads, each suggested replacement costs less per request. Fast costs 80% less than Sonar on BrowseComp and 69% less on DeepSearchQA, and 91% less than Sonar Pro on both. Low costs 63% and 54% less than Sonar Reasoning Pro. High costs 22% and 21% of Sonar Deep Research, which bears out Perplexity's "under a quarter", and low costs about 1% and 2% of it, consistent with Perplexity's "1-2%". The exception is xhigh, Perplexity's top-quality tier rather than its Deep Research replacement: it costs 28% more per request than Deep Research on BrowseComp ($0.78 against $0.611) while scoring 85.33% against 29.10%, and 61% less on DeepSearchQA.
Your queries are not Perplexity's benchmark, so check list prices. Perplexity's pricing calculator assumes a fast run reads 1,000 input tokens and writes 500; it labels these median values from representative runs, not billed values, and lists them beside an older model. At the fast preset's priority rate that is $0.0007 in tokens plus $0.001 for one Fast Search: $0.0017 per request, or $1.70 per 1,000, inside the benchmark's range. Without priority it would be $0.00135. The same token counts on the old Sonar card come to $0.0065 at low search context, $0.0095 at medium and $0.0135 at high. That is rate-card arithmetic at identical token counts, not what the same query cost. Inside the Agent API, at the same token counts, perplexity/sonar with one Fast Search comes to $0.0025, or $0.0040 with standard search. Actual cost is metered per response, and a completed response can report it in its usage cost field.
Rate limits, credits and refunds
Perplexity sells API credits in advance. Usage tiers rise with lifetime purchases and never drop: Tier 1 from $50, Tier 2 from $250, Tier 3 from $500, Tier 4 from $1,000 and Tier 5 from $5,000. Agent API limits apply per organization, shared across models and keys: 1, 3, 8, 17, 33 and 33 requests per second from Tier 0 to Tier 5, so the step from $1,000 to $5,000 of purchases adds no Agent API throughput. The Search API allows 50 query units per second on every tier, and a five-query request is one billed request but five rate-limit units.
If credits run out, Perplexity blocks your API keys until you add more; an optional Automatic Top Up refills the balance when it drops below $2. A Perplexity subscription is not required to use the API. We found no free API allowance on the pricing page or in the API billing help article, and the Pro billing FAQ, modified on 17 October, does not mention the API. The help center, modified on 14 September, says refunds "can be processed" if reported within 14 days of purchase and the credits are unused. The API terms, updated on 23 January 2026, still name "Sonar by Perplexity" and say payments are nonrefundable except where the terms expressly say otherwise.
Building your own: search APIs plus a model
Sonar sold search and an answer in one call. The Agent API already lets you pick a model from several providers and freeze its configuration. If you would rather call a model on your own account, you buy search separately and pay that model to read the results. Per billed call at listed paid rates:
| Route | Listed price | What one call returns | Free allowance |
|---|---|---|---|
| Perplexity Search API | $5 per 1,000 requests, $1 with Fast Search | Ranked web results, up to five queries per request | None found |
| Bright Data SERP API, pay as you go | $1.50 per 1,000 successful requests | Search results from Google, Bing, DuckDuckGo or Yandex as JSON, HTML or Markdown | 5,000 credits a month, shared across its APIs |
| Bright Data SERP API, Scale | $499 a month for 380,000 requests, then $1.30 per 1,000 | Same | Same |
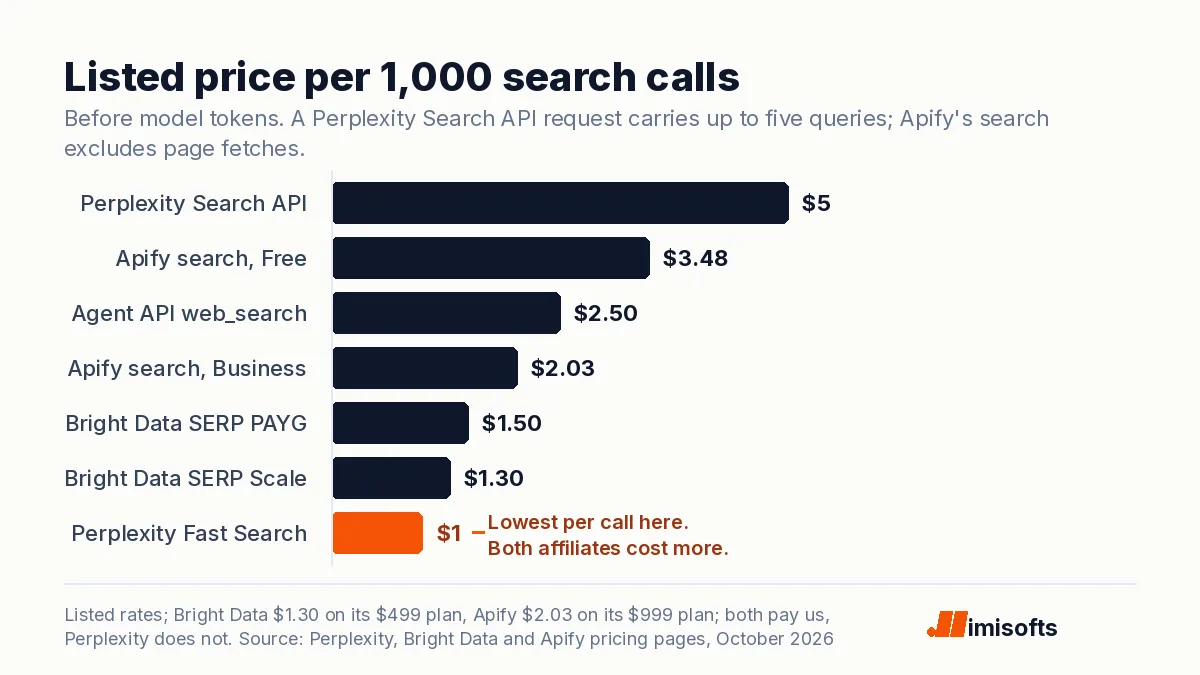
| Apify RAG Web Browser | $3.48 (Free) to $2.03 (Business, $999 a month) per 1,000 searches, plus $2.28 to $1.33 per 1,000 fetched pages | Google results plus up to three pages as Markdown by default | $5 of usage on the Free plan |
At those rates Perplexity's Fast Search is the lowest per call, below both of our affiliates. The units differ, though. A Perplexity request can carry five queries and returns 10 results by default; Bright Data bills per successful request; Apify bills per query and per page fetched, up to three by default, and adds $0.000225 per GB of memory on normal runs. Perplexity also bills successful requests that return nothing, and Apify charges for fetched pages that hold no text. We did not test speed or result quality on any of them.
The comparison that hurts our affiliates most: Perplexity's benchmark lists the fast preset at $0.0014 to $0.0018 per request on its own workloads, $1.40 to $1.80 per 1,000, for a run that returns an answer. Bright Data charges $1.50 per 1,000, or $0.0015 a request, on pay as you go for search results with no answer, so a model adds cost on top. An Apify default query, one search plus up to three pages, costs at most $10.32 per 1,000 on the Free plan through Standby, or $6.02 on the $999-a-month Business plan, before a model reads anything; normal runs add $1.80 per 1,000 at the default 8 GB. Apify's $5 of free usage covers about 484 such queries. Bright Data gives every new account 5,000 free credits a month, one per SERP request, from a pool shared with its other APIs; its menu says "starts from $1/1k req", a rate we could not tie to any plan on its pricing cards.
So the alternatives earn their place for specific jobs. For Google's own results and search verticals such as Shopping, Maps, News or Jobs, use Bright Data's SERP API. For Google's top pages as Markdown, priced the same per page with either of its scraping tools, use Apify's RAG Web Browser. For raw results feeding your own model, Perplexity's Search API with Fast Search is the lowest listed price here, $1 per 1,000 requests. Our AI agent search API comparison prices Tavily, Exa, Brave and others per 1,000 calls, and our Custom Search API alternatives covers raw Google result feeds.
Which Perplexity API route fits which job
- Answers with citations, the old Sonar job: the Agent API's fast preset, or low for light multi-step research. If you freeze fast to pin its model, the changelog says to set the service tier to priority to match it; default processing bills the listed token rate, half the priority rate.
- Deep research reports: high, which Perplexity's benchmark puts at under a quarter of Sonar Deep Research per request. Use xhigh when its higher scores, 85.33% against 78.00% on BrowseComp and 93.00% against 89.60% on DeepSearchQA, are worth about 5.7 and 1.8 times high's cost per request.
- Raw results for your own model or index: the Search API, batching up to five queries per request.
- Google rankings, verticals or page text: Bright Data or Apify, at the prices above.
- Being cited by Perplexity rather than calling it: that is AI search optimization, not an API bill, and you can track Perplexity referrals in GA4.
If you would rather have it built, our AI automation agency can scope the pipeline and cost it before it ships.
Frequently Asked Questions
Perplexity ended support for Sonar Chat Completions on 27 September 2026. Synchronous and streaming calls still work while Perplexity reformulates them as Agent API requests, model by model; asynchronous calls are no longer supported. The Sonar model itself is listed inside the Agent API at $0.25 per million input tokens and $2.50 per million output tokens, with web search billed per call. We could not confirm how reformulated legacy calls are billed.
It depends on the model, the tokens and the tool calls. Perplexity's own benchmark tables list the fast preset at $0.0014 to $0.0018 per request, low at $0.006 to $0.012, high at $0.121 to $0.136 and xhigh at $0.218 to $0.78. At the fast preset's priority rate, twice the listed token price, a fast run of 1,000 input and 500 output tokens with one Fast Search works out to about $0.0017.
We found no free API allowance on Perplexity's pricing page or its API billing help article, read on 19 October 2026. Credits are prepaid, a Perplexity subscription is not required, and new accounts start at Tier 0 with one Agent API request per second. The help center says refunds can be processed if the issue is reported within 14 days of purchase and the credits are unused; the API terms say payments are nonrefundable except where they say otherwise.
Yes, on the Agent API: web_search costs $2.50 per 1,000 invocations, or $1.00 with Fast Search, on top of model tokens, and the search context the model reads is billed as tokens. The Search API works differently: $5 per 1,000 successful requests, or $1 with Fast Search, with no token charges.
Perplexity suggests the fast preset for Sonar and Sonar Pro, low for Sonar Reasoning Pro and high for Sonar Deep Research, as starting points. On Perplexity's own benchmarks, fast costs 91% less per request than Sonar Pro, and high costs 21% to 22% of Sonar Deep Research.
With Fast Search, yes: $1 per 1,000 requests, against $1.50 per 1,000 on Bright Data's SERP API pay as you go and $3.48 to $2.03 per 1,000 searches on Apify's RAG Web Browser before page fetches. At the standard $5 per 1,000 it costs more per call, though one request can carry up to five queries. They return different things: Bright Data returns Google's own results and verticals, Apify returns Google results plus page Markdown.