October 12, 2026. OpenAI's Ultrafast mode for GPT-6.1 Sol costs $12 per million input tokens and $60 per million output tokens, six times the Standard rate of $2 and $10, according to OpenAI's API pricing page. OpenAI's launch post promises near-Astra intelligence at up to 8x the speed of Sol Standard. Since October 8 it is open to all API users, per the API changelog. A request with 3,000 input and 300 output tokens costs $0.009 on Standard and $0.054 on Ultrafast.
Key numbers
| Item | Number |
|---|---|
| GPT-6.1 Sol Ultrafast, input | $12 per 1M tokens |
| GPT-6.1 Sol Ultrafast, cached input | $0.60 per 1M tokens |
| GPT-6.1 Sol Ultrafast, output | $60 per 1M tokens |
| Sol Ultrafast, prompts over 272,000 tokens | $24 in, $90 out per 1M |
| GPT-6.1 Sol Standard | $2 in, $10 out per 1M |
| GPT-6.1 Sol Fast (up to 2.5x faster) | $4 in, $20 out per 1M |
| Ultrafast speed vs Sol Standard (per OpenAI) | up to 8x |
| GPT-6 Astra Ultrafast | $60 in, $300 out per 1M |
| Sol Ultrafast rate limit, Build tier (Launch 4,000,000, Grow 40,000,000) | 1,000,000 tokens a minute |
| Open to all API users since | October 8, 2026 |
| One request, 3,000 in and 300 out | $0.009 Standard, $0.054 Ultrafast |
Prices and limits read on 12 October 2026 from OpenAI's API pricing page, Ultrafast and Fast mode guides, API changelog and launch post; per-request costs at list prices.
What OpenAI shipped on October 8
- A service tier, not a new model. You call gpt-6.1-sol with service_tier set to ultrafast in the Responses API. OpenAI says it reduces the time between generated output tokens.
- Open to every API account, with its own rate limits, separate from Standard and Fast. GPT-6.1 Sol defaults to 1,000,000 tokens a minute on the Build tier, 4,000,000 on Launch and 40,000,000 on Grow, per the Ultrafast guide. We explained those three tiers in OpenAI's new usage tiers.
- GPT-6 Astra has it too, at $60 and $300 per million, with lower limits of 500,000, 1,000,000 and 5,000,000 tokens a minute.
- Long prompts cost more again. Over 272,000 input tokens, Sol Ultrafast is $24 input and $90 output per million for the whole request, the same 2x input and 1.5x output uplift the GPT-6.1 Sol model page applies on every tier.
- Data residency: Sol Ultrafast supports US and EU residency; Astra Ultrafast supports the US only.
- In ChatGPT Work and Codex, access is limited to the $500 Pro plan and eligible Enterprise and Edu workspaces, and Enterprise admins must switch it on.
Latenode's report confirms the $12 and $60 pricing and the plan limits. We covered the August preview, when no price had been published, in OpenAI's Ultrafast preview.
Standard, Fast or Ultrafast: the price of speed
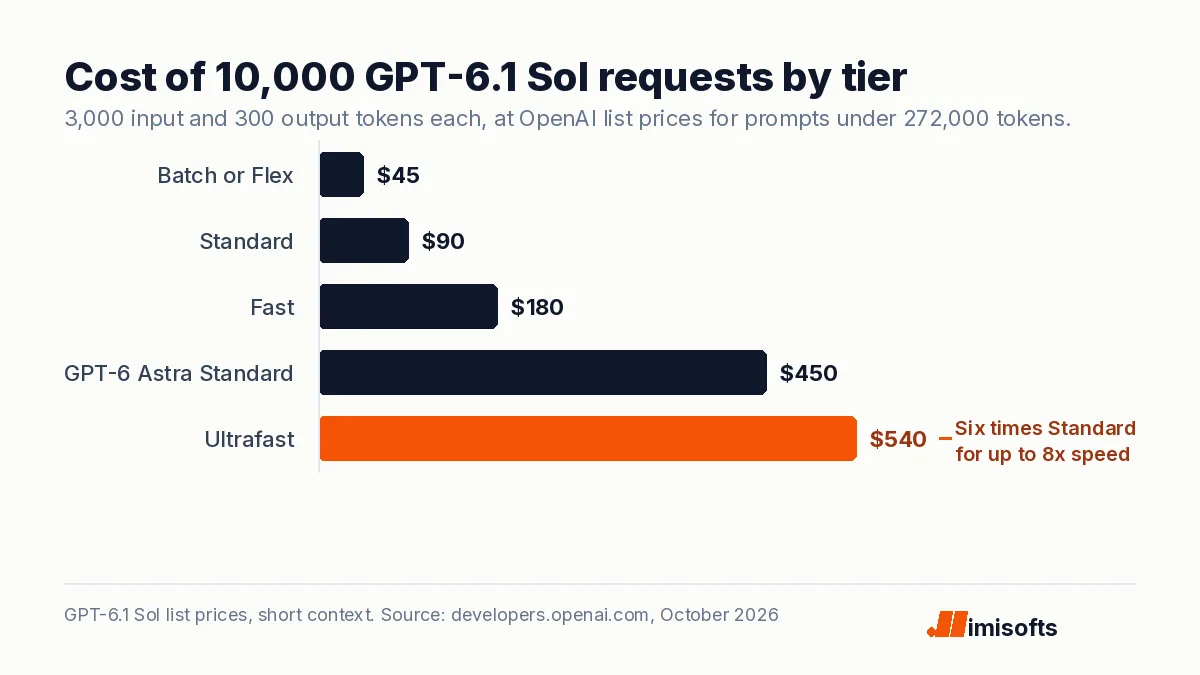
OpenAI now sells GPT-6.1 Sol at three speeds. Standard is $2 and $10 per million. Fast, which replaced priority processing on July 30, is $4 and $20 for up to 2.5x the speed, per OpenAI's Fast mode guide. Ultrafast is $12 and $60 for up to 8x. Batch and Flex sit below at $1 and $5. For 10,000 requests a month at 3,000 input and 300 output tokens:
- Batch or Flex: $45
- Standard: $90
- Fast: $180
- Ultrafast: $540
- GPT-6 Astra on Standard, for comparison: $450
Ultrafast costs three times Fast for a little over three times the speed, 8x against 2.5x, at OpenAI's upper bounds. Measure your own latency before you pay for either.
What it means for operators
Ultrafast is a price paid per token for time saved per answer, so it only pays where a person or a process is waiting on long output. OpenAI's examples are debugging an outage, agents navigating apps and live experiences where every second counts. Bulk work such as enrichment, summaries and lead scoring belongs on Batch at a twelfth of the price. For voice, test before you pay: a phone agent's replies are short, and Ultrafast cuts the time between output tokens, so on a 30-word answer the gain may be small next to speech recognition and text to speech. If you run an AI receptionist for a home-services business, measure end-to-end response time on real calls before moving it to Ultrafast, and use the WebSocket connection OpenAI recommends so network overhead does not eat the gain. Our AI voice agent builds start with that latency test.
Frequently Asked Questions
For GPT-6.1 Sol, $12 per million input tokens, $0.60 for cached input, $15 for cache writes and $60 per million output tokens, six times Standard. Prompts over 272,000 tokens cost $24 and $90. GPT-6 Astra in Ultrafast mode is $60 and $300.
OpenAI says up to 8x faster than GPT-6.1 Sol Standard, with near-Astra intelligence. Fast mode, at twice the Standard price, is up to 2.5x faster. Both are upper bounds, so test with your own prompts.
All OpenAI API users since October 8, 2026, under separate Ultrafast rate limits of 1,000,000 tokens a minute on Build, 4,000,000 on Launch and 40,000,000 on Grow for GPT-6.1 Sol. In ChatGPT Work and Codex it is limited to the $500 Pro plan and eligible Enterprise and Edu workspaces.
Only if your measured latency improves. OpenAI says Ultrafast cuts the time between generated output tokens, and phone replies are short, so speech recognition and text to speech may dominate the delay. Test end-to-end response time on real calls before paying six times Standard.