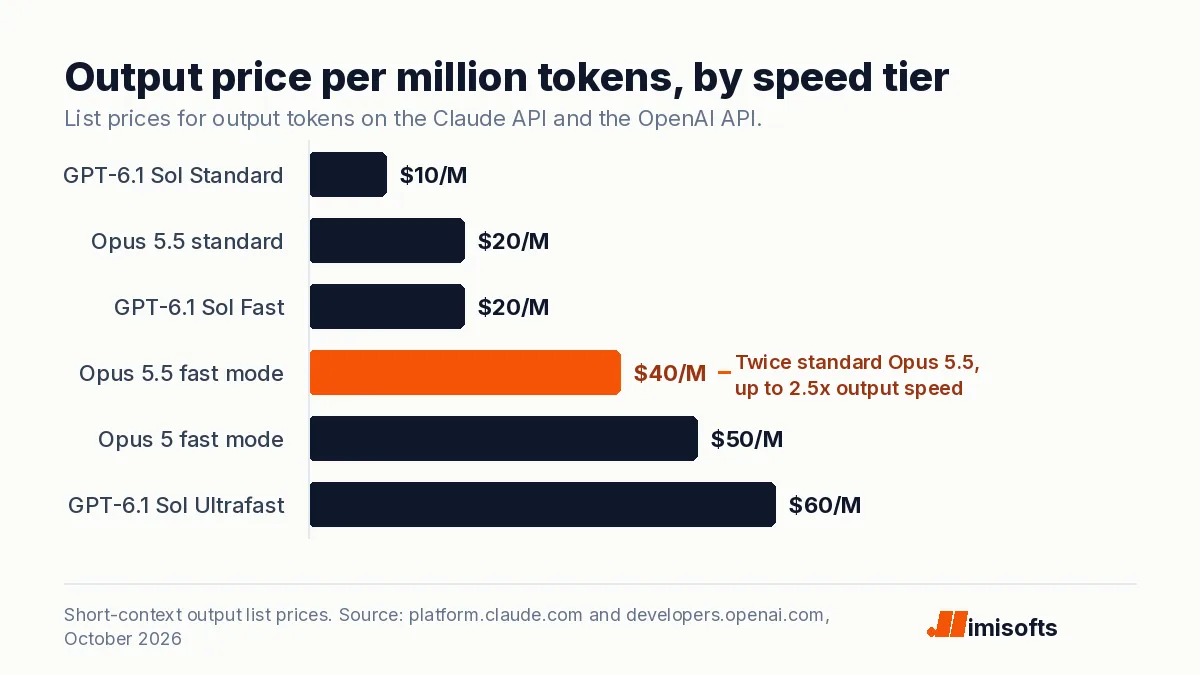
October 16, 2026. Anthropic took fast mode for Claude Opus 5.5 out of research preview on October 15, so any Claude API organization in the Start, Build or Scale usage tier can now send speed: "fast" without an access request or beta header, according to its release notes. Fast mode costs $8 per million input tokens and $40 per million output tokens on Opus 5.5, twice the standard $4 and $20, for up to 2.5 times more output tokens per second, per the fast mode docs and pricing page. An agent task that reads 50,000 tokens and writes 5,000 costs $0.30 at standard speed and $0.60 fast.
Key numbers
| Item | Number |
|---|---|
| Claude Opus 5.5 fast mode, input (standard $4) | $8 per 1M tokens |
| Claude Opus 5.5 fast mode, output (standard $20) | $40 per 1M tokens |
| Claude Opus 5 and Opus 4.8 fast mode (input / output, still research preview) | $10 / $50 per 1M tokens |
| Output speed gain (output tokens per second, not time to first token) | up to 2.5x |
| Opus 5.5 fast mode out of research preview | October 15, 2026 |
| Usage tiers with a default fast mode limit (Start, Build and Scale) | 3 |
| SDK retries on a fast mode 429 error (by default) | 2 |
| Task with 50,000 tokens in and 5,000 out (Opus 5.5 list prices) | $0.30 standard, $0.60 fast |
| OpenAI GPT-6.1 Sol on Fast (twice Standard) | $4 / $20 per 1M tokens |
| OpenAI GPT-6.1 Sol on Ultrafast (six times Standard) | $12 / $60 per 1M tokens |
Prices read on 16 October 2026 from Anthropic's pricing page, fast mode docs, release notes and Claude Code docs, and OpenAI's API pricing page.
What changed on October 15
- No access request for Opus 5.5. Requests no longer need the fast-mode-2026-02-01 beta header, and requests that still send it keep working.
- Default rate limits. Opus 5.5 now has a default fast mode rate limit in the Start, Build and Scale tiers, separate from standard Opus limits. Evaluation tier organizations get it once they move up.
- Older Opus models stay in preview. Fast mode on Claude Opus 5 and Opus 4.8 still needs preview access and the beta header, at $10 per million input and $50 per million output tokens.
- Where it runs. The Claude API, including Managed Agents, and for Opus 5.5 also Microsoft Foundry deployments hosted on Azure. Not Claude Platform on AWS, partner-operated clouds, the Batch API or Priority Tier.
An independent Claude Code guide lists the same $8 and $40 rates, exactly twice standard Opus 5.5.
What the premium buys, and what it does not
Fast mode runs the same model with a faster inference setup, so quality does not change. The premium covers the full context window, including requests over 200,000 input tokens, and caching and data residency multipliers apply on top. Three details decide whether it pays:
- It speeds up output, not the first token. Anthropic says the gain is in output tokens per second, not time to first token. Long answers finish sooner, but it is not built to shorten the pause before the first word, which is the delay a caller hears on a phone agent such as an AI receptionist for home services.
- Switching speed breaks the cache. Fast and standard requests do not share cached prefixes, and Claude Code's docs say turning fast mode on mid-conversation bills the whole context once at the fast, uncached input price. Turn it on at the start of a session.
- It has its own limit. Past the fast mode limit, the API returns a 429 error with a retry-after header, and the SDK retries twice by default, or you can catch it and resend at standard speed.
Why Claude Code says fast mode requires usage credits
On Pro, Max, Team and Enterprise plans, Claude Code's fast mode docs say fast mode is paid only from usage credits, even when plan usage is left. Pro and Max users turn credits on under Settings, then Usage, on claude.ai. On Team and Enterprise, fast mode stays off until an Owner enables it, which is why users see that it has been disabled by their organization. When we read it, that page still called fast mode a research preview needing provisioned access; the API docs say Opus 5.5 needs neither.
How it compares with OpenAI
OpenAI prices speed the same way. Its API pricing page, read on October 16, lists GPT-6.1 Sol at $2 per million input and $10 per million output tokens on Standard, $4 and $20 on Fast, the renamed Priority tier, and $12 and $60 on Ultrafast, six times Standard. Our OpenAI Ultrafast pricing breakdown covers when that tier pays.
When fast mode pays
Pay for it where a person waits on a long answer: a live debugging session, a sales demo or a chat agent that writes long replies. Skip it for overnight jobs, batch processing and phone calls, where the first word matters more than the last. For a client agent, run the same prompts at both speeds and price the gap before you quote. For agents built and costed for you, see our AI automation agency or hire an AI engineer.
Frequently Asked Questions
On Claude Opus 5.5, fast mode costs $8 per million input tokens and $40 per million output tokens, twice the standard $4 and $20. On Claude Opus 5 and Opus 4.8 it is $10 and $50. The rate applies across the full context window, and prompt caching and data residency multipliers apply on top.
Not for Claude Opus 5.5 on the Claude API since October 15, 2026. Organizations in the Start, Build and Scale tiers get a default fast mode rate limit and need no beta header. Fast mode on Opus 5 and Opus 4.8 is still a research preview with a waitlist, and Evaluation tier organizations must move up a tier first.
On Pro, Max, Team and Enterprise plans, fast mode is billed only from usage credits, even when plan usage is left. Pro and Max users turn credits on under Settings, Usage on claude.ai. On Team and Enterprise an Owner must also enable fast mode, otherwise users are told it has been disabled by their organization.
Not by design. Anthropic says fast mode raises output tokens per second by up to 2.5 times and is not aimed at time to first token, so long answers finish sooner but the wait before the first word is not what it shortens.