October 20, 2026. A Claude API organization on the Start tier can send 1,000 requests a minute to Claude Opus 5.5, Sonnet 5.5 or Haiku 5.5, with 2 million input and 400,000 output tokens a minute on each model, but it can spend only $500 in a calendar month before Anthropic pauses its API access until 00:00 UTC on the first of the next month. Those are the figures on Anthropic's rate limits page, read today. Tiers 1 to 4 no longer exist: on June 26 Anthropic consolidated them into Start, Build and Scale and raised Sonnet and Haiku to Opus's limits at every tier, according to its release notes.
Key numbers
| Item | Number |
|---|---|
| Start tier, current Opus, Sonnet and Haiku models (2M input, 400K output tokens a minute) | 1,000 requests a minute |
| Build tier (5M input, 1M output tokens a minute) | 5,000 requests a minute |
| Scale tier (10M input, 2M output tokens a minute) | 10,000 requests a minute |
| Monthly spend cap, Start | $500 |
| Monthly spend cap, Build | $1,000 |
| Monthly spend cap, Scale | $200,000 |
| Fable 5.x on Start (500K input, 100K output tokens a minute) | 1,000 requests a minute |
| Requests per Message Batches batch | 100,000 |
| Tiers consolidated into Start, Build and Scale | June 26, 2026 |
| 10,000-lead run on Opus 5.5, uncached (about $85 with the shared prompt cached) | $180 |
Limits and prices read on 20 October 2026 from Anthropic's rate limits page, release notes and pricing page.
The limits by tier
- Start. 1,000 requests a minute (RPM), 2,000,000 input tokens a minute (ITPM) and 400,000 output tokens a minute (OTPM) on every current Opus, Sonnet and Haiku model. Monthly spend cap: $500.
- Build. 5,000 RPM, 5,000,000 ITPM and 1,000,000 OTPM. Monthly spend cap: $1,000.
- Scale. 10,000 RPM, 10,000,000 ITPM and 2,000,000 OTPM. Monthly spend cap: $200,000. Custom limits above Scale have no cap and are arranged with Anthropic's account team.
- Fable 5.x is lower. Claude Fable 5.1 and Fable 5 share one bucket, at 1,000 RPM, 500,000 ITPM and 100,000 OTPM on Start.
- Each model has its own bucket. Opus 5.5, Opus 5, Sonnet 5.5 and Sonnet 5 each have a separate limit, so work split across models gets each model's full allowance.
- New accounts can start lower. Organizations with little usage history may begin in an Evaluation tier below these limits, which rises automatically as history builds.
- Batches have their own limits. The Message Batches API allows 1,000, 2,000 and 4,000 RPM by tier, up to 200,000, 300,000 and 500,000 requests waiting in the queue, and 100,000 requests per batch.
What counts toward the limits
On current models only uncached input counts toward input tokens per minute, so in Anthropic's own example a 2,000,000 ITPM limit with an 80 percent cache hit rate processes 10 million input tokens a minute. Output counts as it is generated and max_tokens is ignored, so a generous max_tokens costs nothing. A normal 429 error names the limit you crossed. The spend cap behaves differently: it returns the same rate_limit_error type with no retry-after header and the code enforced_spend_limit_reached, and retries, including the SDK's automatic ones, fail until access resumes.
What a 10,000-lead personalization run needs
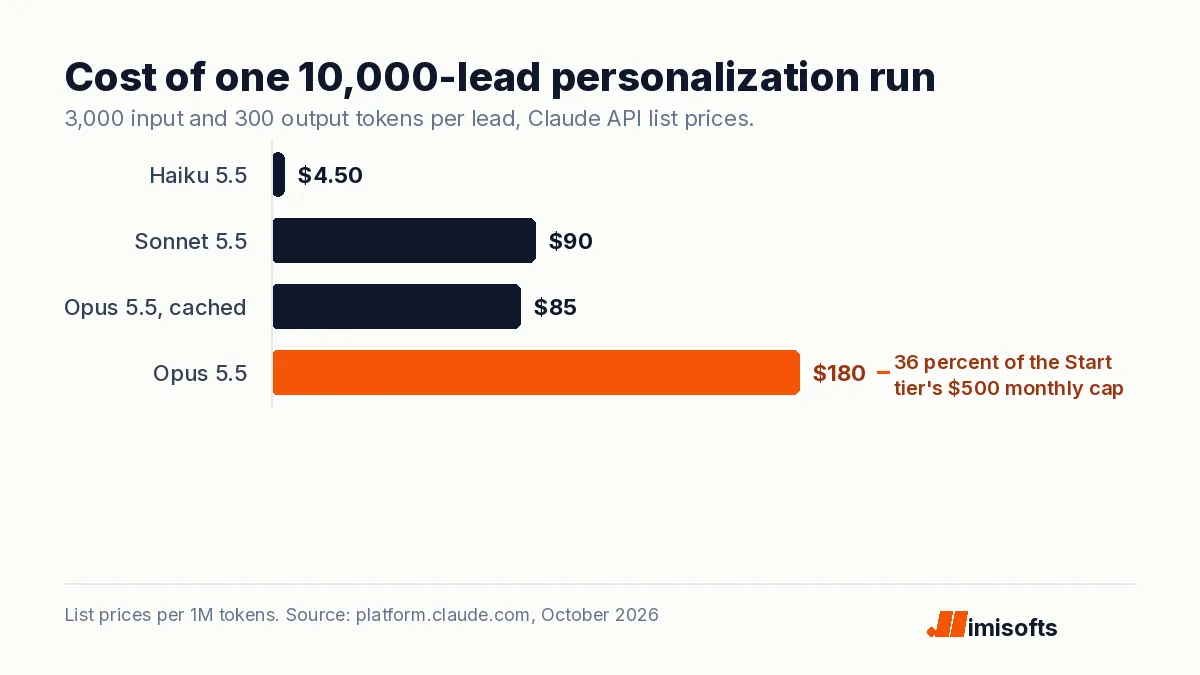
Take a cold email job writing an opening line for 10,000 leads: 3,000 input tokens a lead, 2,500 of them a shared prompt, and 300 output tokens. On Start, 1,000 RPM means at least 10 minutes. Without caching, 30 million input tokens against 2 million a minute stretch that to 15 minutes; cache the shared prompt and uncached input falls to 5 million, so requests per minute set the pace again. At list prices from Anthropic's pricing page, the run costs about $4.50 on Haiku 5.5, $90 on Sonnet 5.5 and $180 on Opus 5.5, or about $85 on Opus with the shared prompt cached. One uncached Opus run uses 36 percent of the Start tier's $500 cap, and a third run in the same month would hit the cap partway through.
What it means for operators
Check your tier on the Rate limits page in the Claude Console before a client launch, set your own spend limit below the cap on the Billing page, and alert on enforced_spend_limit_reached so a paused account is not mistaken for a busy one. Use Request tier increase before a heavy month, not during it. Cache system prompts and tool definitions, which raises throughput and cuts cost, and move work that can wait to the Message Batches API. Agents such as OpenClaw that run on your own Claude API key draw on the same organization limits; our OpenClaw setup service and AI engineers configure them, and an intake agent like our AI intake for law firms should never go quiet late in the month because of a cap.
Our OpenAI API usage tiers brief covers the same limits at OpenAI, and cached input token pricing explains the caching math. To skip the pipeline entirely, see what a cold email agency costs per month.
Frequently Asked Questions
On the Start tier, 1,000 requests, 2 million input tokens and 400,000 output tokens a minute on each current Opus, Sonnet and Haiku model. Build raises that to 5,000, 5 million and 1 million, and Scale to 10,000, 10 million and 2 million, per Anthropic's rate limits page read on October 20, 2026.
API requests return HTTP 429 with the error code enforced_spend_limit_reached and no retry-after header until 00:00 UTC on the first day of the next month, unless you move to a higher tier. The monthly caps are $500 on Start, $1,000 on Build and $200,000 on Scale.
Not on current models. Uncached input tokens and tokens written to the cache count toward input tokens per minute, but cache reads do not. Claude Haiku 3.5, now retired except on Google Cloud, is the exception. Output tokens count as they are generated, and max_tokens is ignored.
Use Request tier increase on the Rate limits page in the Claude Console, or contact Anthropic support for urgent needs. Organizations also move up tiers automatically as they build usage history, and limits above Scale are arranged with Anthropic's sales team.