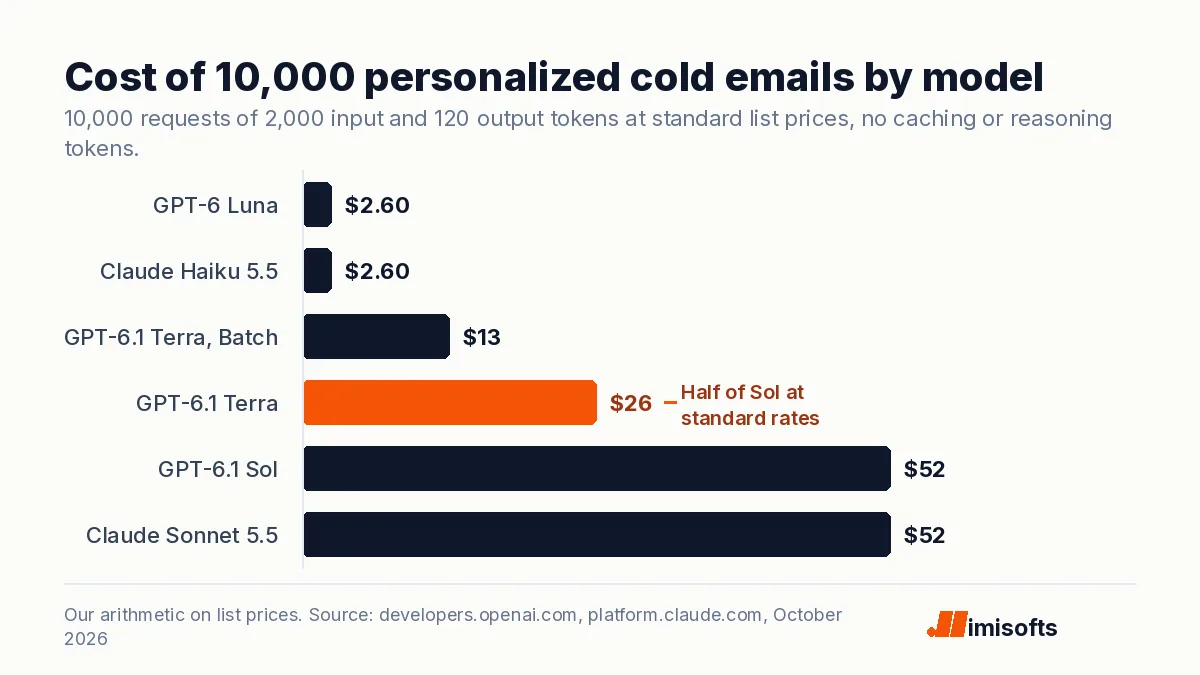
October 27, 2026. OpenAI released GPT-6.1 Terra on 26 October 2026 at $1 per million input tokens, $0.05 per million cached input tokens and $5 per million output tokens, which OpenAI says is 50 percent below the standard prices of GPT-5.6 Terra and GPT-6.1 Sol. It is pitched at visual reasoning, computer use and "clear, natural writing", the middle of an outbound stack: personalized first lines, reply drafts and CRM notes. At list price, 10,000 personalized openers of 2,000 input and 120 output tokens each cost about $26 on Terra and $13 through the Batch API, against $52 on GPT-6.1 Sol and $2.60 on GPT-6 Luna, before any reasoning tokens.
Key numbers
| Item | Number |
|---|---|
| GPT-6.1 Terra input, per million tokens | $1.00 |
| GPT-6.1 Terra cached input, per million tokens | $0.05 |
| GPT-6.1 Terra output, per million tokens | $5.00 |
| Cache write, 30-minute or 12-hour retention (per million tokens) | $1.25 or $2.50 |
| Batch and Flex discount | 50 percent |
| Prompts over 272K input tokens | 2x input, 1.5x output |
| Context window | 1,050,000 tokens |
| GPT-6.1 Sol input and output, per million tokens | $2 and $10 |
| GPT-6 Luna input and output, per million tokens | $0.10 and $0.50 |
| 10,000 personalized emails on Terra ($13.00 through Batch, no caching) | $26.00 |
| Build tier rate limit | 5,000 RPM, 1M TPM |
Prices and limits read on 27 October 2026 from OpenAI's GPT-6.1 Terra model page, API changelog and launch post, and Anthropic's pricing page; the email cost is our arithmetic.
What GPT-6.1 Terra costs
The model page and OpenAI's launch post list these terms, and MarkTechPost's launch report gives the same standard rates:
- Standard rates: $1.00 input, $0.05 cached input and $5.00 output per million tokens. Cache writes cost $1.25 per million with 30-minute retention and $2.50 with 12-hour retention.
- Long prompts: above 272K input tokens, the whole request is billed at 2x the input and cache rates and 1.5x output.
- Discounts and premiums: Batch and Flex are 50 percent lower, Fast mode costs 2x Standard and regional processing adds 10 percent where available.
- Limits: a 1,050,000-token context window and 128,000 max output tokens. There is no free tier; the Build tier allows 5,000 requests and 1 million tokens a minute, Launch 10,000 and 4 million, Grow 15,000 and 40 million.
- Where it runs: the API as gpt-6.1-terra, plus ChatGPT Work and Codex for Plus, Pro, Enterprise and Edu users.
How it compares for writing at volume
Against the models agencies already use for personalization, Terra sits in the middle. GPT-6 Luna and Claude Haiku 5.5 cost $0.10 input and $0.50 output per million tokens (Haiku at that rate for prompts up to 100,000 tokens), and GPT-6.1 Sol and Claude Sonnet 5.5 cost $2 and $10, per OpenAI's API changelog and Anthropic's pricing page, so the 10,000-email job above costs $2.60 on Luna or Haiku and $52 on Sol or Sonnet. OpenAI's case for Terra is accuracy: on its internal benchmark of error-inducing prompts, the error rate at low reasoning effort fell from 53.6 percent with GPT-5.6 Terra to 16.7 percent with GPT-6.1 Terra. OpenAI still points the most complex coding work to GPT-6.1 Sol and GPT-6 Astra.
The catch: reasoning tokens bill as output
Terra's reasoning effort defaults to medium and runs from none to max. OpenAI's reasoning guide says reasoning tokens are not visible but are billed as output tokens, so at the default setting the bill depends on how much the model thinks, not only on the 120 visible tokens. For short copy, set effort to none or low and cap max_output_tokens.
What it means for operators
- Test before you switch. Run 200 real prospects through Terra and Luna and pay Terra's rate only where replies show the difference.
- Batch the bulk work. Personalization is not real time, so the Batch API halves the bill.
- Put shared instructions first so repeated prompt prefixes bill at the $0.05 cached rate.
- Price voice separately. GPT-Live sessions bill $0.05 a minute, and the backend model they delegate to is billed on top at its normal rates; see our GPT-Live pricing breakdown and how we build AI calling for home services.
- Cheaper copy does not fix deliverability. Inbox placement still depends on your domains and email infrastructure.
We wire these models into outbound and CRM workflows as an AI automation agency and run the cold email campaigns they write for. For the caching math, see our OpenAI prompt caching pricing guide.
Frequently Asked Questions
$1 per million input tokens, $0.05 per million cached input tokens and $5 per million output tokens at standard rates. Cache writes cost $1.25 per million with 30-minute retention and $2.50 with 12-hour retention, and prompts over 272K input tokens bill at 2x input and 1.5x output.
Yes. GPT-6.1 Sol lists at $2 input and $10 output per million tokens, so Terra is half the price at standard rates. OpenAI still recommends Sol and GPT-6 Astra for the most complex coding tasks.
Yes. OpenAI prices Batch and Flex 50 percent below Standard, so bulk jobs such as overnight email personalization cost half. Fast mode costs twice Standard.
About $26 at standard list prices if each request uses 2,000 input tokens and 120 output tokens with no caching or reasoning tokens, or about $13 through the Batch API. The same job costs about $52 on GPT-6.1 Sol and $2.60 on GPT-6 Luna.