October 12, 2026. Google's introductory price for Gemini 3.8 Flash ends on December 31, 2026. From January 1, 2027 the model costs $1.50 per million input tokens and $7.50 per million output tokens, twice today's $0.75 and $3.75, according to the Gemini API pricing page and the footnote to Google's September 2 launch post. Gemini 3.6 Flash is on the same schedule. For an automation that sends 10,000 requests a month at about 2,000 input and 500 output tokens, the bill goes from $33.75 to $67.50 without a line of code changing. And since October 8, Google routes every gemini-3.7-flash request to 3.8 Flash, per its API changelog, so workflows still pinned to the older model already run on the one that doubles.
Key numbers
| Item | Number |
|---|---|
| Gemini 3.8 Flash input, through Dec 31, 2026 (introductory price) | $0.75 per 1M tokens |
| Gemini 3.8 Flash input, from Jan 1, 2027 | $1.50 per 1M tokens |
| Gemini 3.8 Flash output, through Dec 31, 2026 (thinking tokens included) | $3.75 per 1M tokens |
| Gemini 3.8 Flash output, from Jan 1, 2027 | $7.50 per 1M tokens |
| Gemini 3.6 Flash ($0.75 and $3.75, then $1.50 and $7.50) | same schedule |
| Batch and Flex, from Jan 1, 2027 (half of Standard) | $0.75 in, $3.75 out per 1M |
| Cached input, from Jan 1, 2027 (storage $1.00 per 1M tokens per hour) | $0.15 per 1M tokens |
| Gemini 3.8 Flash TTS audio, from Jan 1, 2027 ($0.00225 today) | $0.0045 per 10 seconds |
| Gemini 3.5 Flash-Lite (no January change listed) | $0.30 in, $2.50 out per 1M |
| Gemini 3.8 Live spoken output (no January change listed) | about $0.018 a minute |
| Deep Research preview agent shutdown (deep-research-pro-preview-12-2025) | October 23, 2026 |
| 10,000 requests a month, 2,000 in and 500 out | $33.75 today, $67.50 from Jan 1 |
Prices and dates read on 12 October 2026 from Google's Gemini API pricing page, API changelog and deprecations page, and the 2 September Gemini 3.8 Flash launch post; per-workload costs at list prices.
What changes on January 1, 2027
Every dated price on Google's pricing page doubles on New Year's Day: the two current Flash models, the two Flash speech models and Gemini Robotics ER 2 Preview, a model few agencies run. DataCamp's review of Gemini 3.8 Flash reports the same schedule.
- Gemini 3.8 Flash, Standard: input goes from $0.75 to $1.50 per million tokens and output from $3.75 to $7.50. Google bills thinking tokens at the output rate, so a model that reasons before it answers pays the higher price on those tokens too.
- Gemini 3.6 Flash, Standard: the identical $0.75 and $3.75 today, then $1.50 and $7.50.
- Batch and Flex: half of Standard on both models, $0.375 and $1.875 today, $0.75 and $3.75 from January 1.
- Priority: $1.35 and $6.75 today, $2.70 and $13.50 from January 1.
- Context caching: cached input goes from $0.075 to $0.15 per million tokens, and storage from $0.50 to $1.00 per million tokens per hour.
- Gemini 3.8 Flash TTS: text input goes from $0.50 to $1.00 per million tokens and audio output from $9.00 to $18.00 per million, which Google equates to $0.00225 and then $0.0045 per 10 seconds of speech. Gemini 3.8 Flash-Lite TTS goes from $6.00 to $12.00, or $0.0015 to $0.003 per 10 seconds.
What does not change
The same page lists no January change for Gemini 3.5 Flash-Lite ($0.30 input and $2.50 output per million tokens), Gemini 3.1 Flash-Lite ($0.25 and $1.50 for text) or the Gemini 3.8 Live voice model ($3.00 per million audio input tokens, about $0.005 a minute, and $12.00 per million audio output tokens, about $0.018 a minute). Grounding with Google Search stays at 5,000 free requests a month, shared across Gemini 3 and newer models, then $14 per 1,000.
| Model, paid tier, per 1M tokens | Through Dec 31, 2026 | From Jan 1, 2027 |
|---|---|---|
| Gemini 3.8 Flash | $0.75 in, $3.75 out | $1.50 in, $7.50 out |
| Gemini 3.6 Flash | $0.75 in, $3.75 out | $1.50 in, $7.50 out |
| 3.8 Flash on Batch or Flex | $0.375 in, $1.875 out | $0.75 in, $3.75 out |
| Gemini 3.5 Flash-Lite | $0.30 in, $2.50 out | No change listed |
| Gemini 3.1 Flash-Lite | $0.25 in, $1.50 out | No change listed; shuts down May 7, 2027 |
| Gemini 3.8 Live, audio output | $12.00 | No change listed |
The October 8 routing change behind the deadline
Google's changelog entry of October 8 deprecated two Flash models and pointed their traffic at newer ones automatically, and the deprecations page lists the dates operators now have to plan around:
- gemini-3.7-flash: deprecated, with requests routed to gemini-3.8-flash. Google launched 3.8 Flash on September 2 at the same introductory price as 3.7 Flash, so the routing changes the model, not today's price. No shutdown date has been announced.
- gemini-3.5-flash: deprecated, with requests routed to gemini-3.6-flash, which doubles in January along with 3.8 Flash.
- Deep Research agent: deep-research-pro-preview-12-2025 shuts down on October 23, 2026. Google's replacements are deep-research-preview-04-2026 and deep-research-max-preview-04-2026.
- gemini-3.1-flash-tts-preview: shuts down on November 17, 2026, with 3.8 Flash TTS or 3.8 Flash-Lite TTS as the replacements, both of which double about six weeks later.
- gemini-3.1-flash-lite: shuts down on May 7, 2027, replaced by 3.5 Flash-Lite.
What 10,000 requests a month cost before and after
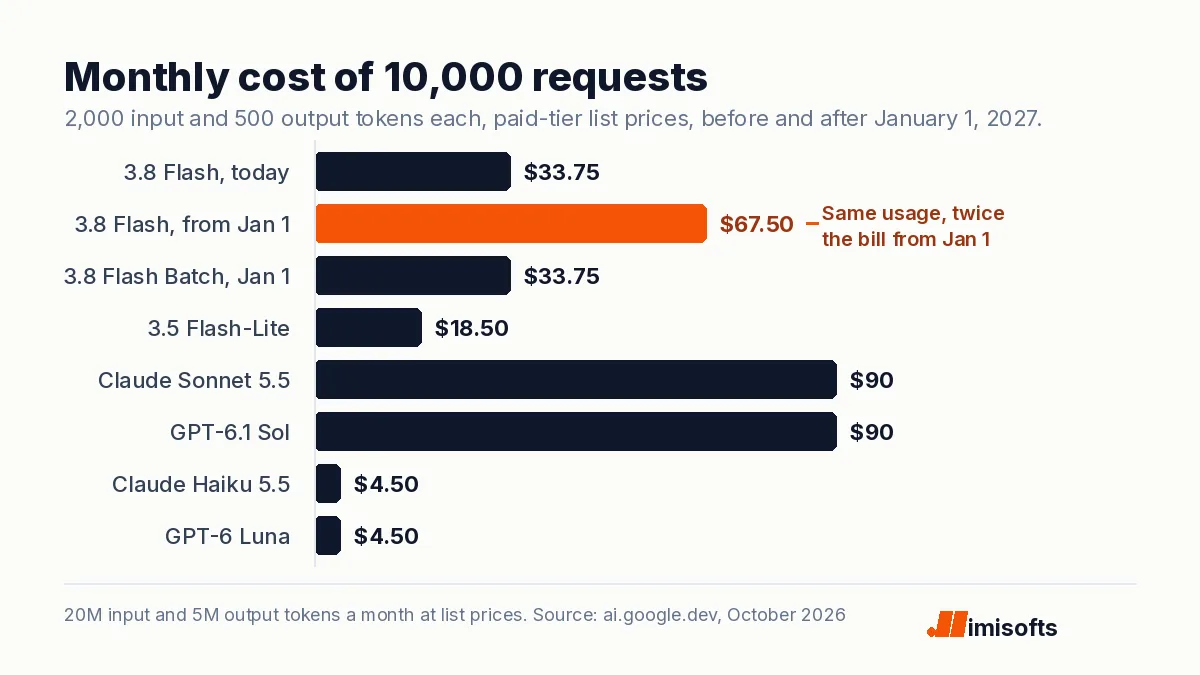
Take a typical agency workflow: an n8n or Make scenario that classifies an inbound lead, drafts a reply and writes a summary to the CRM, run 10,000 times a month at about 2,000 input tokens and 500 output tokens each, thinking included. That is 20 million input and 5 million output tokens a month. At list prices:
- Gemini 3.8 Flash today: $15.00 for input plus $18.75 for output, $33.75 a month.
- Gemini 3.8 Flash from January 1: $30.00 plus $37.50, $67.50 a month.
- Gemini 3.8 Flash on Batch or Flex from January 1: $33.75, the same as today's Standard bill.
- Gemini 3.5 Flash-Lite: $6.00 plus $12.50, $18.50 a month, with no January change listed.
- Claude Sonnet 5.5 and GPT-6.1 Sol, both $2 and $10 per million at list price on Anthropic's pricing page and OpenAI's pricing page: $90.00 a month.
- Claude Haiku 5.5 and GPT-6 Luna, both $0.10 and $0.50 per million: $4.50 a month.
So even at $1.50 and $7.50, Gemini 3.8 Flash stays a quarter below the mid-tier models from Anthropic and OpenAI at list price, while the small models we priced in Claude Haiku 5.5 pricing cost a fraction of either for routing and extraction. The jump matters less inside one workflow than as a line item multiplied across every client account an agency runs on Flash.
Voice agents: speech doubles, Live audio does not
If an AI receptionist for a home-services business, like the ones we compare for an AI answering service for HVAC, speaks through Gemini 3.8 Flash TTS, its voice gets twice as expensive. At 1,000 calls a month with 90 seconds of agent speech each, 1,500 minutes of audio cost $20.25 today and $40.50 from January 1. Flash-Lite TTS moves from $13.50 to $27.00. Gemini 3.8 Live, the speech-to-speech model, lists no January change: about $0.018 a minute for its spoken output, $27.00 for the same 1,500 minutes, plus about $0.005 a minute for the caller's audio. Those are different architectures, so test call quality before switching on price alone. We break down the rest of a call in what an AI receptionist costs, and build these stacks as AI voice agents.
What it means for operators
Three things change on January 1 without anyone touching a workflow. Budgets set in the fourth quarter on today's rates cover half of what the same usage costs in the first quarter. Fixed-fee automation retainers priced on 3.8 Flash lose margin on the first invoice of the year. And any client still calling gemini-3.7-flash or gemini-3.5-flash is now served by 3.8 Flash or 3.6 Flash, both on the January schedule, so the model string in an old workflow no longer tells you which model, or which price list, you are on. The opportunity sits in the same table: Batch and Flex at half price, 3.5 Flash-Lite at a fifth of the January input price, and cache reads at a tenth of input.
How to cut the January bill before it lands
- Inventory model strings. List every workflow, its model and its monthly tokens from the usage dashboard, including anything still on 3.7 Flash or 3.5 Flash.
- Move work nobody waits for to Batch or Flex. Lead enrichment, nightly summaries and bulk classification at half price cost in January what Standard costs today.
- Send simple steps to Flash-Lite. Routing, tagging and extraction often pass on Gemini 3.5 Flash-Lite at $0.30 and $2.50. Run your own test set first.
- Cache the shared prompt. A long system prompt or knowledge block read on every call costs $0.15 per million as a cache read from January, against $1.50 uncached.
- Watch thinking tokens. They bill at the output rate, so a routine step that reasons at length pays $7.50 per million for it.
- Re-price retainers now. Show clients the January number before the invoice does.
If you would rather hand the audit off, our n8n developers re-route model calls inside existing workflows, and our AI automation agency team re-prices client stacks across Gemini, Claude and OpenAI.
What we do not know yet
Google has not said whether the introductory rate could be extended, and it has announced no shutdown date for gemini-3.7-flash or gemini-3.5-flash. The prices here are the Gemini Developer API's paid-tier list prices as read on October 12, 2026.
Frequently Asked Questions
On January 1, 2027. Google's introductory price for Gemini 3.8 Flash expires on December 31, 2026, per the footnote to its September 2 launch post, and the Gemini API pricing page lists the same date for Gemini 3.6 Flash and the 3.8 Flash speech models.
$1.50 per million input tokens and $7.50 per million output tokens on the Standard paid tier, up from $0.75 and $3.75. Batch and Flex requests cost half that, $0.75 and $3.75, and cached input costs $0.15 per million.
Yes. Gemini 3.6 Flash has the same $0.75 and $3.75 introductory rate and the same $1.50 and $7.50 price from January 1, and the Batch, Flex and Priority rates for both models double on the same date.
Google deprecated gemini-3.7-flash on October 8, 2026 and now routes its requests to gemini-3.8-flash automatically. 3.8 Flash launched at the same introductory price as 3.7 Flash, so the routing does not change today's list price, and the model those requests now reach doubles in price on January 1. No shutdown date has been announced.
Google's pricing page lists no January change for Gemini 3.5 Flash-Lite ($0.30 and $2.50 per million tokens), Gemini 3.1 Flash-Lite ($0.25 and $1.50, shutting down May 7, 2027) or Gemini 3.8 Live (about $0.005 a minute of audio in and $0.018 a minute out). Grounding with Google Search also stays at $14 per 1,000 requests after 5,000 free a month.
Move jobs that do not need an instant answer to Batch or Flex, which cost half of Standard, route simple steps to Gemini 3.5 Flash-Lite, cache long shared prompts and limit thinking on routine steps. Batch alone brings a 3.8 Flash workload back to today's Standard price.