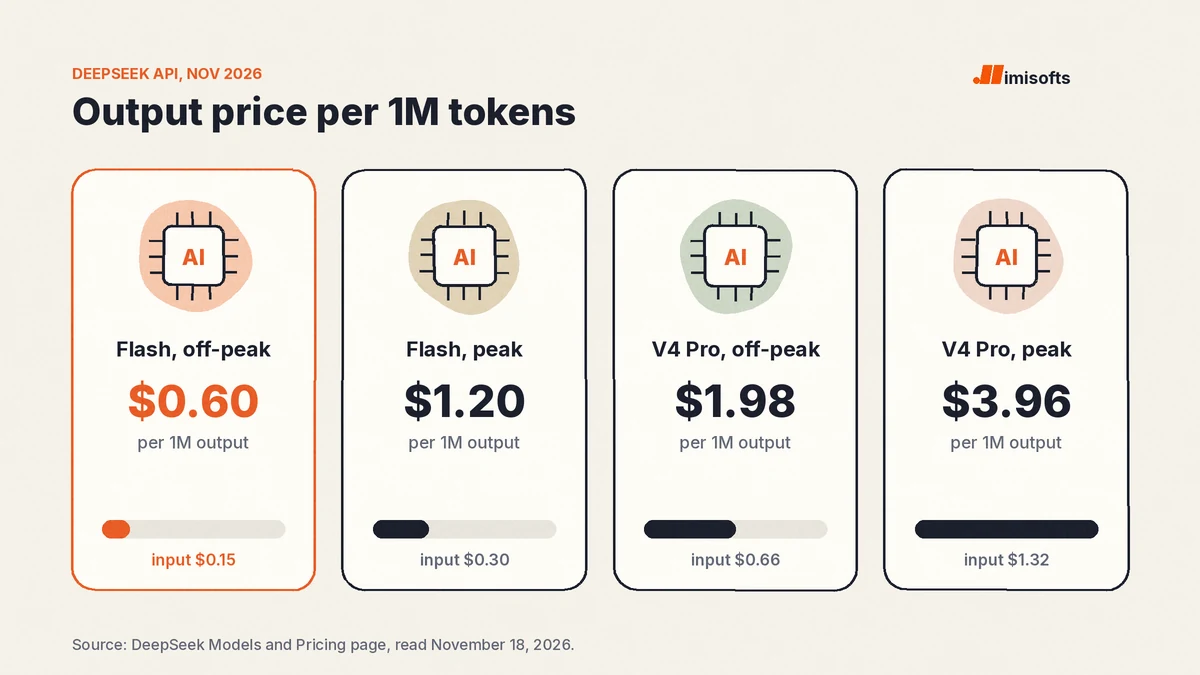
Short answer. The DeepSeek API charges per 1 million tokens, and the price depends on the hour. Off-peak, deepseek-flash costs $0.15 per 1M input tokens, $0.003 when the input is a cache hit, and $0.60 per 1M output tokens; deepseek-v4-pro costs $0.66 in and $1.98 out. During peak hours (01:00 to 04:00 and 06:00 to 10:00 UTC, Monday to Friday) every rate doubles, according to DeepSeek's Models and Pricing page.
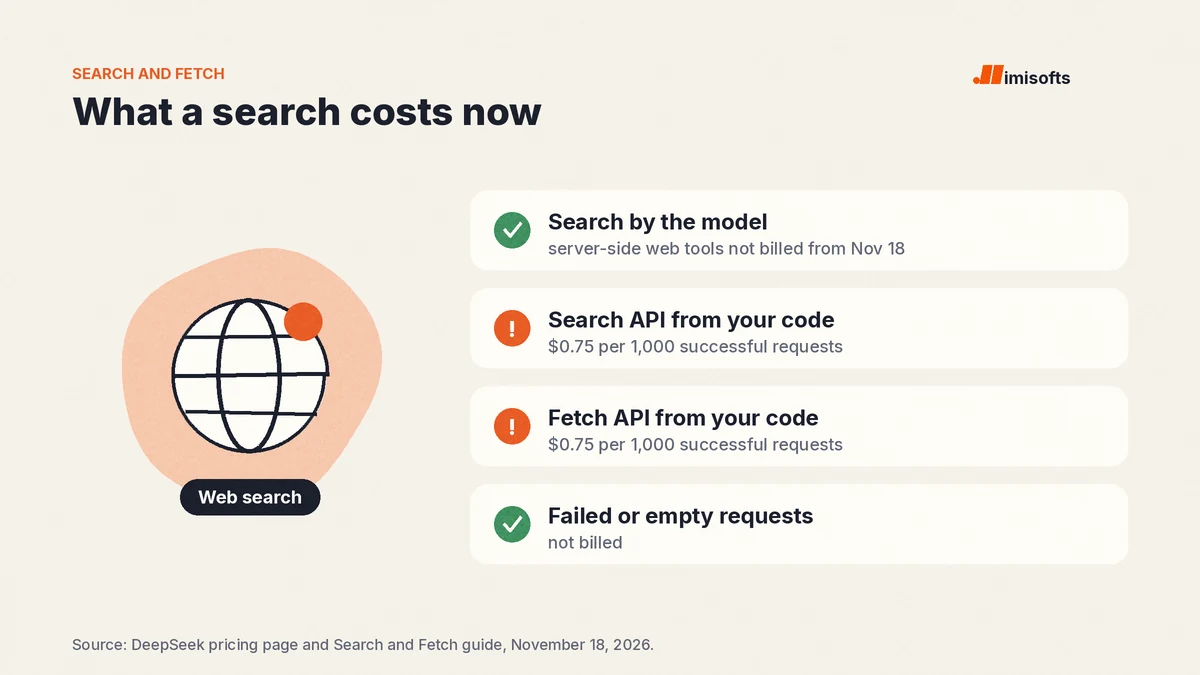
One change is dated today. From 12:00 Beijing time on November 18, 2026 (04:00 UTC), searches and page fetches that the model runs through DeepSeek's server-side web tools are no longer billed; you pay only for tokens. Calling the standalone Search or Fetch API from your own code still costs $0.75 per 1,000 successful requests.
Below are the full rate card, the peak hours in US and Dubai time, a worked monthly cost for one agent, and the limits that come with each model. If you want an agent built on the cheapest model that does the job, our AI automation team scopes that with you. Prices were read on November 18, 2026.
Key numbers
| Item | Number |
|---|---|
| deepseek-flash input, off-peak (cache miss; $0.003 on a cache hit) | $0.15 per 1M |
| deepseek-flash output, off-peak ($1.20 at peak) | $0.60 per 1M |
| deepseek-v4-pro input, off-peak (cache miss; $0.022 on a cache hit) | $0.66 per 1M |
| deepseek-v4-pro output, off-peak ($3.96 at peak) | $1.98 per 1M |
| Peak hours (Monday to Friday; off-peak is half price) | 01:00 to 04:00 and 06:00 to 10:00 UTC |
| Search and Fetch APIs (successful requests, called from your code) | $0.75 per 1,000 |
| Server-side web tools (from November 18, 2026, 04:00 UTC) | Not billed |
| Concurrency limit (deepseek-flash / deepseek-v4-pro, per account) | 2,500 / 500 |
| Context window (maximum output 384K) | 1M tokens |
DeepSeek API Docs: Models and Pricing, Change Log, Search and Fetch, Rate Limit and Isolation, Context Caching. Read November 18, 2026.
DeepSeek API prices per 1M tokens
DeepSeek sells two models through the API. The table shows every token rate on its pricing page, in US dollars per 1 million tokens.
| Rate per 1M tokens | deepseek-flash off-peak | deepseek-flash peak | deepseek-v4-pro off-peak | deepseek-v4-pro peak |
|---|---|---|---|---|
| Input, cache hit | $0.003 | $0.006 | $0.022 | $0.044 |
| Input, cache miss | $0.15 | $0.30 | $0.66 | $1.32 |
| Output | $0.60 | $1.20 | $1.98 | $3.96 |
Both models have a 1M token context window and a maximum output of 384K tokens. deepseek-flash runs the DeepSeek-V4.1-Flash-1017 version and accepts images; deepseek-v4-pro runs DeepSeek-V4-Pro-0813 and does not support vision. Pro costs 4.4 times as much as Flash for uncached input and 3.3 times as much for output.
Thinking counts as output. DeepSeek's web tools guide counts thinking tokens within output_tokens, and the pricing page bills output tokens, so reasoning is billed at the output rate.
Peak and off-peak hours in your time zone
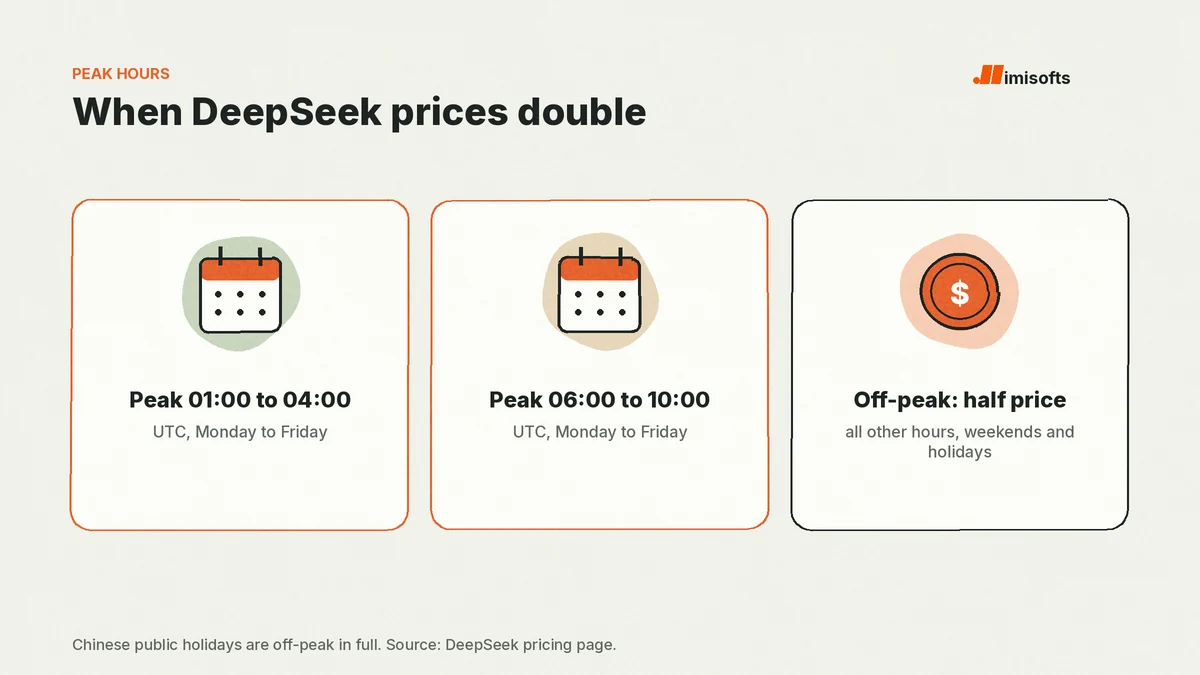
DeepSeek moved to peak and off-peak pricing on August 16, 2026, at 16:00 UTC, its change log says. Off-peak rates are half of peak. The pricing page defines the windows this way: "Peak hours are 01:00 - 04:00 and 06:00 - 10:00 UTC, Monday through Friday, excluding Chinese public holidays." Weekends and Chinese public holidays are off-peak in full.
| Peak window (UTC) | US Eastern (standard time) | US Pacific (standard time) | Dubai (UTC+4) |
|---|---|---|---|
| 01:00 to 04:00, Mon to Fri | 8 pm to 11 pm, Sun to Thu | 5 pm to 8 pm, Sun to Thu | 5 am to 8 am, Mon to Fri |
| 06:00 to 10:00, Mon to Fri | 1 am to 5 am, Mon to Fri | 10 pm to 2 am, Sun to Thu night | 10 am to 2 pm, Mon to Fri |
For a US team the peak windows fall mostly in the evening and overnight, so daytime work runs at the off-peak rate. In the UAE the second window covers late morning and early afternoon on weekdays. We suggest moving batch jobs, such as enriching a lead list or summarizing call recordings, to the weekend or to hours outside both windows.
Cache hits: the cheapest tokens you can buy
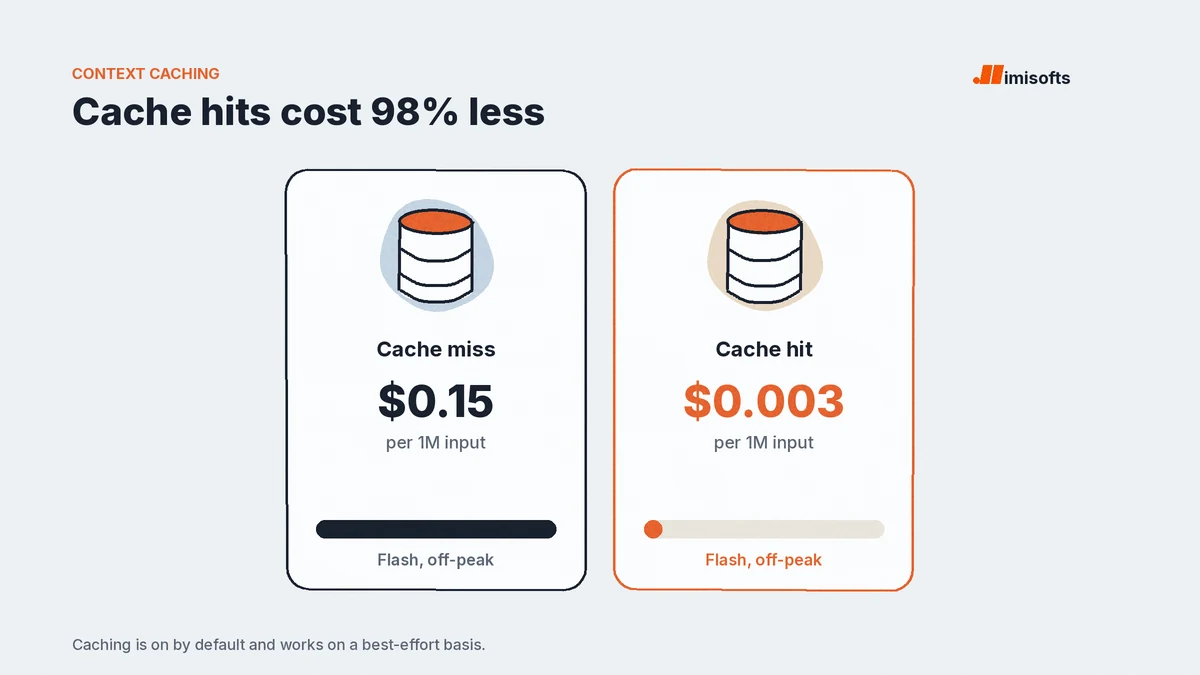
Context caching is on by default for every account, according to DeepSeek's context caching guide. When a new request starts with the same prefix as an earlier one, that part can be served from the cache and billed at the cache hit rate: $0.003 per 1M tokens on Flash off-peak, 98% below the $0.15 cache miss rate. On Pro the cache hit rate of $0.022 is about 96.7% below $0.66.
Three details decide how often you get the lower rate:
- Keep the start of the prompt identical. Put the fixed system prompt and instructions first and the changing part (the lead, the email, the transcript) last, so repeated input can be served from the cache.
- Check the usage fields. Each response reports prompt_cache_hit_tokens and prompt_cache_miss_tokens.
- Do not budget on 100%. DeepSeek says the cache works on a "best-effort" basis, takes seconds to build and is cleared automatically, "usually within a few hours to a few days".
Search, Fetch, OCR and speech prices
Beyond tokens, DeepSeek sells tools by the request, the page, the hour or the character. The November 13 release added web search, file input and URL reading, plus standalone Search and Fetch, OCR, speech to text and text to speech APIs.
| Item | Unit | Price |
|---|---|---|
| Search API (text) | 1,000 successful requests | $0.75 |
| Fetch API | 1,000 successful requests | $0.75 |
| Server-side web tools (search, image search, page fetch by the model) | per call | Not billed from November 18, 2026; tokens only |
| File parsing and OCR API | 1,000 pages | $0.225 |
| Speech to text (ASR) | 1 hour of audio | $0.058 limited-time (list $0.116) |
| Text to speech (TTS) | 10,000 characters | $0.225 limited-time (list $0.45) |
The speech rates matter most for phone agents, which turn a caller's audio into text and the reply back into speech, such as AI calling for home service businesses. At the limited-time rates, 100 hours of transcription cost $5.80 and 1 million characters of speech cost $22.50.
The difference between the first two rows and the third matters. The Search and Fetch guide says searches the model runs through server-side tools are not billed, and names the web tools, the web_search tool in the Responses API, Web Search in Claude Code, and search in DeepSeek Harness when its provider is set to "DeepSeek (Legacy)". Calls your own client makes to the Search and Fetch APIs are billed, including search in DeepSeek Harness when its provider is "DeepSeek Search API".
For the standalone APIs you pay only for a request that returns HTTP 200 with a result. Failed requests, empty results and timeouts are free, and asking for 50 results costs the same as asking for one. Our news story on the DeepSeek Search API launch covers the October terms in detail.
What one agent costs a month on each model
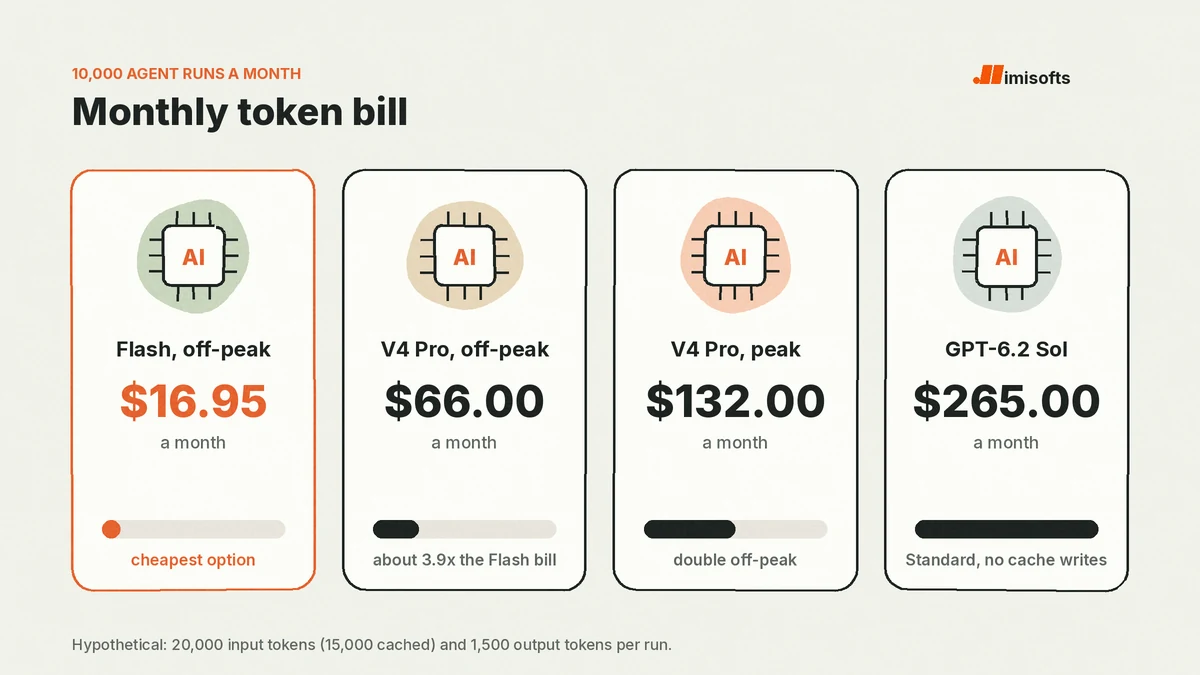
Here is a hypothetical workload: a lead research agent that runs 10,000 times a month. Each run sends 20,000 input tokens, of which 15,000 are a fixed prompt that hits the cache and 5,000 are new, and gets 1,500 output tokens back. That is 150M cache hit tokens, 50M cache miss tokens and 15M output tokens a month.
| Model and hours | Cache hit | Cache miss | Output | Monthly total |
|---|---|---|---|---|
| deepseek-flash, off-peak | $0.45 | $7.50 | $9.00 | $16.95 |
| deepseek-flash, peak | $0.90 | $15.00 | $18.00 | $33.90 |
| deepseek-v4-pro, off-peak | $3.30 | $33.00 | $29.70 | $66.00 |
| deepseek-v4-pro, peak | $6.60 | $66.00 | $59.40 | $132.00 |
| OpenAI gpt-6.2-sol, Standard | $15.00 | $100.00 | $150.00 | $265.00 |
The OpenAI row uses the Standard rates on OpenAI's API pricing page: $2.00 input, $0.10 cached input and $10.00 output per 1M tokens for gpt-6.2-sol. It leaves out OpenAI's cache write charges, so the real gap is wider. The table compares price only, not answer quality, which you should test on your own prompts. Our GPT-6.2 pricing guide and the AI model API price comparison cover the other vendors.
If the same agent also called the standalone Search API twice per run, that would add 20,000 requests, or $15.00 a month. Letting the model search through the server-side web tools instead (on deepseek-flash) costs nothing extra from today, apart from the tokens the results add to the context.
Concurrency and rate limits
DeepSeek limits how many requests run at once. Its rate limit page and the Search and Fetch guide set these account-level limits:
- deepseek-flash: 2,500 concurrent requests.
- deepseek-v4-pro: 500 concurrent requests.
- Search API: 100 requests a second. Fetch API: 25 requests a second, plus a per-domain limit.
Requests above a limit get HTTP 429. On raising the concurrency limit, DeepSeek says "There is no additional cost for capacity expansion." A request that has not started inference after 10 minutes is closed by the server.
Why other pages show different DeepSeek prices
You will find older numbers, including on DeepSeek's own site. On November 18, 2026, the API platform page at deepseek.com still listed "DeepSeek-V4-Flash" at $0.14 per 1M input tokens and $0.28 per 1M output tokens, with a note that "Prices may change" and a pointer to the API docs. DeepSeek's change log says V4 Flash was retired on September 10, 2026, when V4.1 Flash launched, and the pricing page bills the old model names at the Flash price. We treat the API docs as the rate card.
Old model names cause the same confusion. deepseek-chat and deepseek-reasoner were set to be discontinued on July 24, 2026, according to the April 24 change log entry. Today the Flash model name is deepseek-flash; deepseek-v4-flash and deepseek-v4-flash-vision-exp are still accepted and billed at the Flash price.
The pricing page says fees are deducted from a topped-up balance or a granted balance, granted first, and it does not describe a free tier. US companies should also read our guide on whether DeepSeek is banned in the US before routing customer data to it.
How imisofts can help
imisofts is a Dubai-based agency that builds AI automation and AI voice agents. We can estimate token use for your workflow, compare DeepSeek, OpenAI and other models on your own prompts, and schedule batch jobs into off-peak hours where the data rules allow it. If you are also pricing a customer-facing assistant, our guide to AI chatbot costs for a business shows the other line items. To talk it through, contact our AI automation agency team.
Frequently Asked Questions
Off-peak, deepseek-flash costs $0.15 per 1M input tokens ($0.003 on a cache hit) and $0.60 per 1M output tokens. deepseek-v4-pro costs $0.66 in and $1.98 out. Peak-hour rates are double.
DeepSeek's pricing page does not describe a free tier; it bills tokens and deducts fees from a topped-up or granted balance. Searches the model runs through its server-side web tools are not billed from November 18, 2026.
01:00 to 04:00 and 06:00 to 10:00 UTC, Monday to Friday, excluding Chinese public holidays. All other hours are off-peak at half price. In US Eastern standard time the windows are 8 pm to 11 pm (Sunday to Thursday) and 1 am to 5 am (Monday to Friday).
Than gpt-6.2-sol on list price, yes. For a hypothetical agent with 10,000 runs a month, deepseek-flash off-peak comes to $16.95 against $265.00 for OpenAI's gpt-6.2-sol at Standard rates, before OpenAI's cache write charges. Test quality on your own prompts.
On deepseek-flash off-peak, 1M input tokens cost $0.15 (or $0.003 if served from the cache) and 1M output tokens cost $0.60. On deepseek-v4-pro off-peak they cost $0.66 and $1.98.
$0.75 per 1,000 successful requests, and the same for the Fetch API, when your own code calls them. Failed requests, empty results and timeouts are not billed. Searches the model runs through server-side web tools are free from November 18, 2026.